Blog
Mistral Large 4 Hardware Guide: Can You Run It Locally?
Mistral Large 4 is a 1.05T-parameter open-weight MoE model. Estimated memory per quantization, which hardware can hold it, and what to do before weights land.
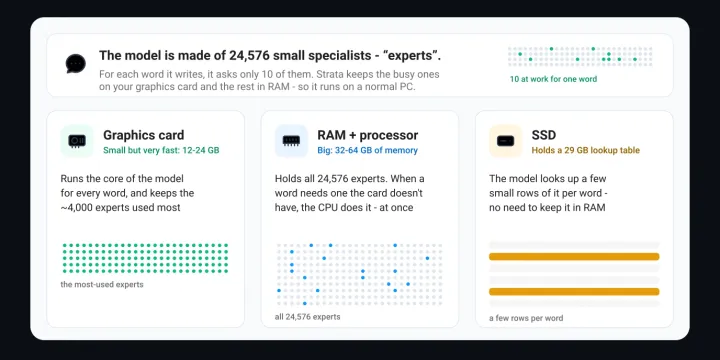
Strata: Run Qwen3.8-Flash-Next (125B) on a 12GB GPU
Strata runs the 125B Qwen3.8-Flash-Next on a 12GB gaming GPU at 50 to 94 tokens per second. The RAM, VRAM, and SSD you need, measured speeds, and the catches.
Unified Memory PCs for Local LLMs: DGX Spark, Mac, Ryzen AI
DGX Spark, RTX Spark, Mac Studio M5, and Ryzen AI Max compared for running big local LLMs: memory size, bandwidth, real 2026 prices, and when a GPU still wins.
AMD ROCm 10: Performance, Windows Support, vs ROCm 7
ROCm 10 explained for home AI builders: what the 3.3x performance claim really measured, Windows support today, the new ROCm CLI install path, and whether to buy AMD.
Best AI Workstation Motherboard 2026: AM5 vs TRX50 vs WRX90
The best motherboards for an AI workstation in 2026: real AM5, TRX50, and WRX90 boards compared on PCIe lanes, x16 GPU slots, and RAM ceilings for 1 to 4 GPUs.
Cloud GPU vs Local GPU in 2026: When to Rent, When to Buy
GPU prices are at record highs. We run the break-even math on renting vs buying an RTX 4090, RTX 5090, or H100 for deep learning, with real monthly costs.
PyTorch Mixed Precision Training: FP16 vs BF16 Guide
How PyTorch's Automatic Mixed Precision works, when to use FP16 vs BF16, GradScaler explained, and which GPUs actually get a speedup.
Ollama Multi-GPU Setup: Split Big LLMs Across 2+ GPUs
Ollama splits a model across GPUs automatically once it outgrows one card. The env vars that control it, mixing VRAM sizes, why NVLink isn't needed, and real builds.
Qwen3.8-27B VRAM Requirements: Which GPU Runs It Locally
Qwen3.8-27B needs about 14.3-17.6 GB at 4-bit, so one 24GB GPU runs it. Full VRAM table from 1-bit to BF16, the cheapest 12GB setup, and RTX 4090 vs 5090.

AirLLM: Run a 70B LLM on a 4GB GPU (and the Catch)
AirLLM runs a 70B model on a 4GB GPU by streaming layers from disk instead of loading them into VRAM. How it works, real VRAM numbers, and the speed cost.

DeepSeek V4 Flash Hardware Guide: VRAM and GPU Requirements
What it takes to run DeepSeek V4 Flash locally: memory needs per quantization, realistic setups from a single 24GB GPU to multi-GPU rigs, and when cloud makes more sense.

Best Jarvis Labs Alternatives 2026: Cloud GPUs Compared
Looking for a Jarvis Labs alternative? RunPod, Vast.ai, Lambda, and Paperspace compared on H100 price per hour, notebook UX, and GPU availability.
Data Analytics Workstation Build 2026: Python, R, SQL
Build a data analytics workstation for pandas, Polars, dask, R, and large SQL datasets: CPU, RAM, storage, and GPU picks at October 2026 prices.

Deep Learning GPU Benchmarks 2026: RTX 5090 vs A100 vs H100
Deep learning GPU benchmarks for 2026: training throughput, inference speed, and VRAM across RTX 5090, 5080, 5070 Ti, A100, and H100, with the best pick per workload.

JAX vs PyTorch 2026: Benchmarks and When to Use Each
JAX vs PyTorch benchmarks for 2026: training throughput on ResNet-50, BERT, and GPT-style models, memory use, and a clear guide to which one to pick.

GLM-5.2 Hardware Guide: VRAM and GPU Requirements
What it takes to run GLM-5.2 locally: memory needs per quantization, realistic setups from Mac Studio to multi-GPU rigs, and when cloud makes more sense.
Best Prebuilt AI Workstations 2026: Top ML Systems
The best prebuilt AI workstations of 2026 by budget, with October 2026 price estimates. Systems from Puget, System76, BOXX, Dell, and HP compared.
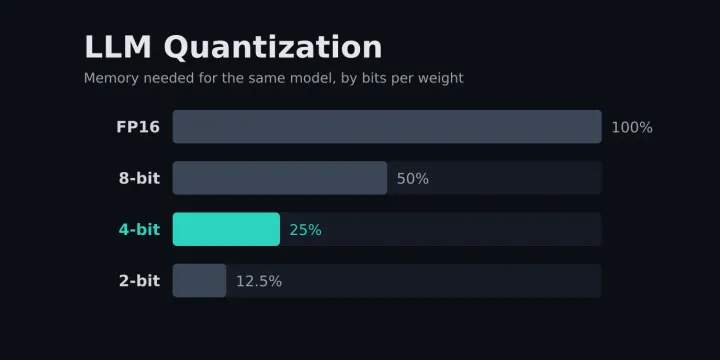
LLM Quantization Explained: GGUF vs GPTQ vs AWQ (2026 Guide)
GGUF vs GPTQ vs AWQ quantization for local LLMs explained. Which format to use with Ollama, llama.cpp, and vLLM, and how much quality you lose.

RTX 5090 vs RTX 4090 for Deep Learning: Is the Upgrade Worth It?
RTX 5090 vs RTX 4090 for deep learning: VRAM, bandwidth, training speed, and whether the upgrade makes sense at October 2026 street prices.

Best CPU for AI and Deep Learning Workloads (2026)
Top CPUs for AI workstations in 2026. Threadripper vs Ryzen vs Intel Core Ultra for deep learning, local LLM inference, and multi-GPU training.

Best NVMe SSD for AI and ML Workloads (2026 Guide)
Top NVMe SSDs for AI dataset storage and ML training in 2026. PCIe 5.0 vs 4.0, read benchmarks, and which drives actually speed up training.

How Much RAM for Local LLMs? The Complete 2026 Guide
Exact RAM requirements for running LLMs locally with Ollama, llama.cpp, and LM Studio. Covers 7B to 70B+ models, CPU offloading, context windows, and DDR5 vs DDR4.

Fix CUDA Out of Memory in PyTorch: 10 Proven Solutions
Diagnose and fix RuntimeError: CUDA out of memory in PyTorch. Batch size, mixed precision, gradient checkpointing, and 7 more proven solutions.

How Much VRAM for FLUX Image Generation? Complete Guide
Exact VRAM requirements for FLUX.1 Dev, Schnell, and Pro models. Benchmarks across RTX 3060, 4090, and 5090 with quantization options for every GPU budget.

Best GPU for Llama 4 Locally: Scout & Maverick Guide
Hardware requirements for running Llama 4 Scout (109B) and Maverick (400B) locally. VRAM needs, quantization, and GPU picks for every budget.
AI Workstation Build Guide 2026: Parts, Prices, Sample Builds
How to build an AI workstation in 2026: GPU, CPU, motherboard, RAM, and PSU picks at real late-2026 prices, three sample builds, and when prebuilt or cloud wins.

PyTorch vs TensorFlow vs JAX: 2026 Framework Comparison
Compare PyTorch, TensorFlow, and JAX for GPU training in 2026: performance benchmarks, VRAM efficiency, deployment, and which framework fits your workload.

Best GPU for Deep Learning 2026: Picks at Every Budget
The best GPUs for deep learning in late 2026, with real street prices: RTX 5090, 5070 Ti, used RTX 3090, AMD RX 9070 XT, and when renting an H100 beats buying.